Can We Stop the Backtest Yet? Why Adaptive Agents Overfit, and How Anytime-Valid Promotion Protects Your Live Account

When is a backtest actually "finished," and when is it just being tortured until it confesses a fake edge?
A ground-breaking quantitative paper published in November 2026 ("Can We Stop the Backtest Yet? Anytime-Valid Promotion Tests for Adaptive Financial Research Agents", arXiv: 2611.01855) addresses one of the most persistent and damaging issues in algorithmic research: the over-optimization of historical data by both human quants and adaptive AI research agents.
🔍 The Over-Optimization Hazzard: Over-Testing Failure Modes
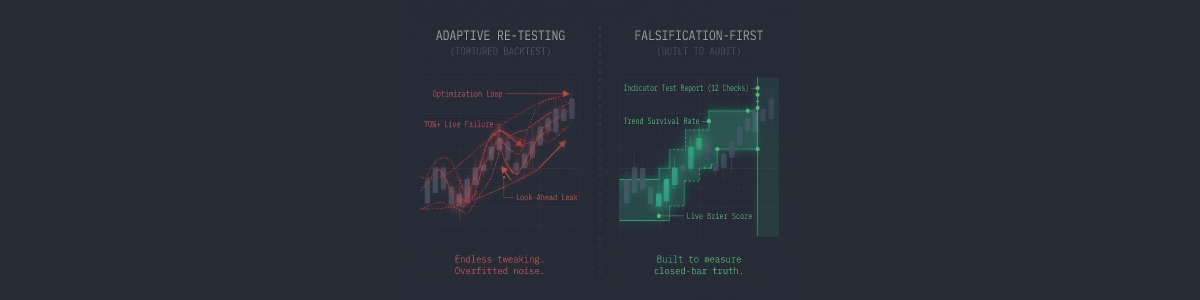
- The Re-testing Trap: If you test and tweak a strategy endlessly on the same data, you are no longer discovering an edge. You are simply extracting noise and look-ahead bias that will inevitably disappear on a live server.
- Why Stats Fail: Traditional significance tests (like standard p-values) assume you only tested a strategy once. In modern automated search workflows, where models run hundreds of iterations, these metrics entirely break down.
- Anytime-Valid Stopping Rules: Researchers used martingale-based e-processes to show that strict, adaptive mathematical stopping rules can prevent research processes from "over-mining" historical backtests, preserving out-of-sample survival rates.
Falsification-First: The Remedy for Backtest Inflation
For automated system design, re-running a strategy tester visual over and over hoping for a smoother equity curve is a sure way to lose money in live markets. In our workflow, we treat every result and indicator behavior as a temporary artifact until it is verified against real, closed-bar transitions and subjected to strict probability calibration.
Edge is not a smooth historical backtest line; it is how often your structural assumptions and states remain valid under live, finalized bars. Measuring these survival states provides a real metric of persistence without the traps of multiple-testing bias.
Tools for Auditing Indicator Integrity and Survival States
Relying on out-of-sample data is not a guarantee if you do not measure the actual metrics of state persistence. Every utility I design on MQL5 and MetaTrader 5 is designed as a strict, non-repainting measurement tool, enabling developers to audit historical behaviors without optimization illusions:
📐 TREND PERSISTENCE — Measuring how often states survive to the next bar
- ▸ Trend Survival States (MT5) · 🆓 · 5-state structural classification
- ▸ Trend Survival Rate (MT5) · $99 · Adds the empirical bar-to-bar survival rate and a live Brier forecast score to monitor model calibration
🔬 MEASUREMENT — Point it at any indicator to audit what it actually does
- ▸ Indicator Test Report (MT5) · 🆓 · MT4 Version (🆓) — Runs twelve rigorous diagnostics to verify that closed-bar values are final and nothing is leaking from tomorrow
👉 Explore all 18 measurement tools on my MQL5 profile: mql5.com/en/users/naamo (@naamo)
🛠️ That is why I built Trend Survival Rate and the Indicator Test Report: instead of torturing historical backtests for a prettier curve, measure closed-bar integrity and live Brier calibration directly on the chart.
📚 References & Further Reading:
- Can We Stop the Backtest Yet? Anytime-Valid Promotion Tests for Adaptive Financial Research Agents (arXiv: 2611.03384, Nov 2026): https://arxiv.org/abs/2611.03384




